Accuracy Transparency
Two separate questions: does Deslop report the right duplicates, and what does its duplication percentage measure? This page answers both, with links to every report behind the numbers.
Read the English transcript
Read the project total
I expand the Duplication section to read the project total. Deslop shows how many lines it analysed and how many it found in repeated code. The percentage describes those files; it does not tell me that a cleanup is automatically safe.
Follow the file counts
I open the file rows behind that total and inspect the highlighted code. This lets me connect the number to real source lines. When I review a result, I want to understand which files were checked and what work was counted.
Check the actual copies
Next I put the reported copies side by side. I check that they really repeat the same work and look at their differences. This is the evidence I use to decide what deserves attention, rather than treating a percentage as a verdict.
See what an exclusion changes
I exclude a folder in the settings file and save it. The sidebar updates because those files are no longer part of the analysis. Before comparing two results, I check settings like this so I know that both runs measured the same files.
How accuracy is measured
Deslop is scored against clone registers: pairs of code ranges from pinned open-source repositories that a reviewer judged by reading the source.
- CLEARLY IN is a real duplicate. Not reporting it is a false negative.
- CLEARLY OUT is not a duplicate. Reporting it is a false positive.
- NOT CLEAR is recorded but scored neither way.
The latest scorecard, from 15 November 2026, covers 47 repositories in 11 languages:
| Measure | Result |
|---|---|
| Judged pairs scored correctly | 1,579 of 1,619 (97.5%) |
| Real duplicates missed (false negatives) | 29 |
| Non-duplicates reported (false positives) | 11 |
| Judged lines covered by the reported copies | 99.2% |
Every remaining miss and false positive is listed by file and line in the scorecard and is still treated as a bug. The corpus contract defines the scoring. These results cover the judged pairs only; they are not a promise of the same precision and recall on every repository.
Pair correctness and coverage answer different questions. A pair is correct when both judged ranges appear in one reported finding. Coverage checks how much of those ranges the finding includes, so reporting a short fragment of a long copy counts as found but lowers coverage.
Accuracy bugs fixed
Every confirmed false positive or false negative is filed on GitHub with the false-positive, false-negative or lane/accuracy label, and gets a test that fails until it is fixed. An issue is closed only after the fix is checked on a released build.
On 21 August 2026 the public issue graph held 33 open accuracy issues, the largest workstream:
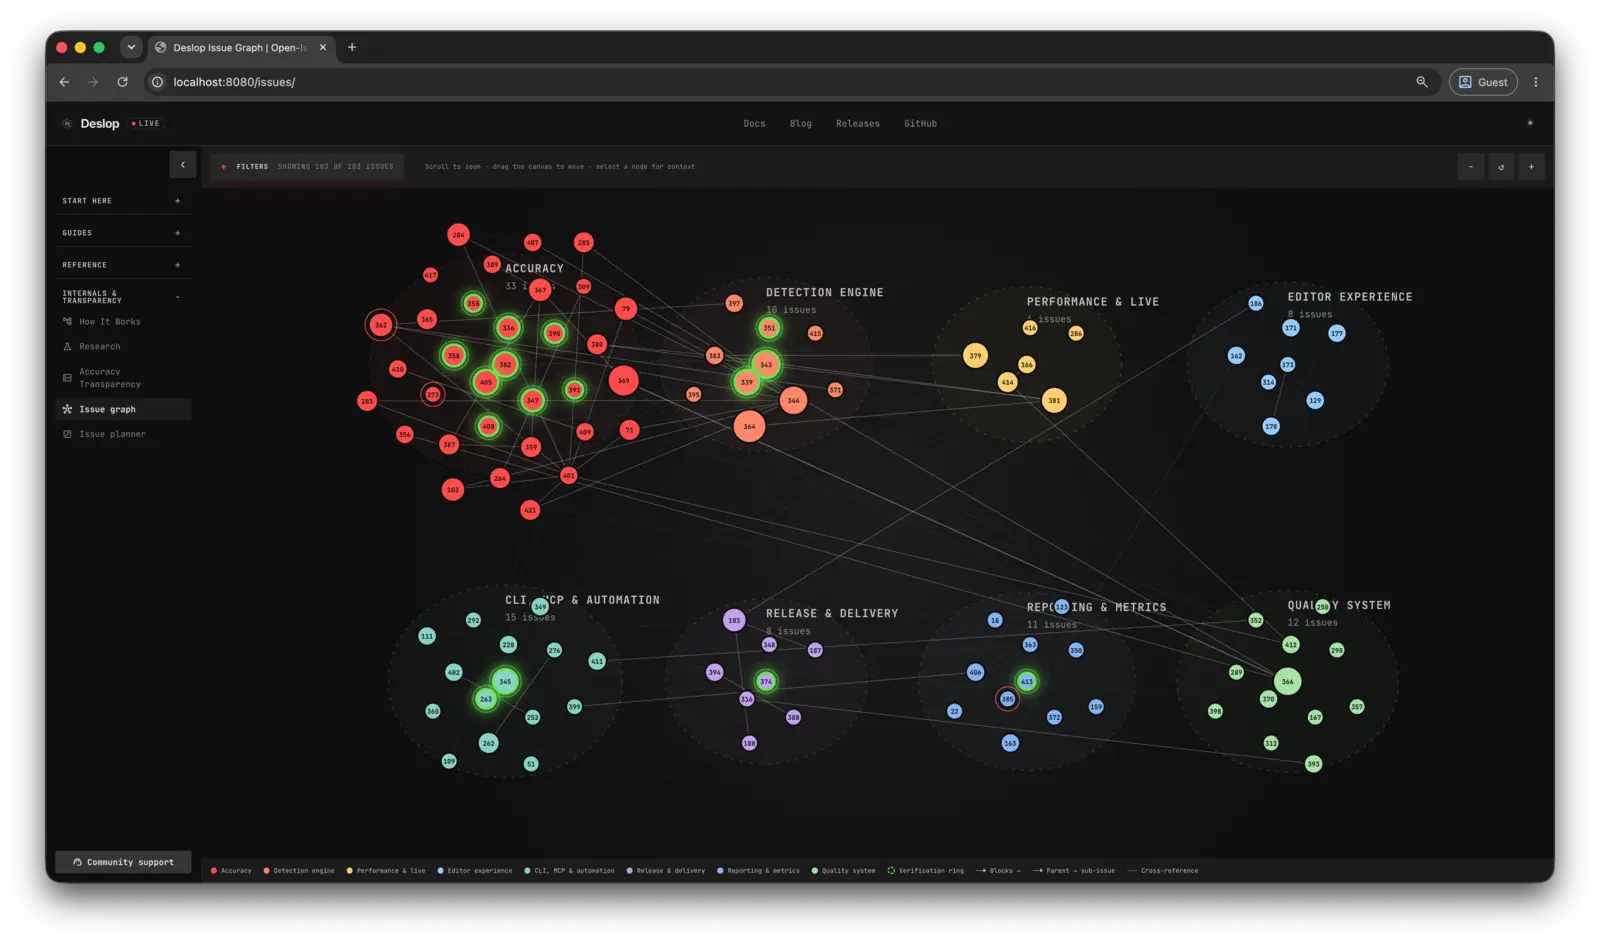
As of 15 November 2026, 48 accuracy issues have been fixed and closed and 29 remain open:
| Month closed | Accuracy issues fixed |
|---|---|
| August 2026 | 1 |
| September 2026 | 31 |
| October 2026 | 4 |
| November 2026 (to the 15th) | 12 |
The fixes include unrelated boilerplate ranked as the top duplicate, renamed copies that were never reported, long copies cut into short fragments, and unrelated clusters sharing one id. The open ones are in the issue graph and the issue planner.
Compared with jscpd
Deslop and jscpd 5.4.3 were run on the same 11 corpus repositories and scored the same way: a judged pair counts as found when one reported group overlaps both of its ranges.
| Judged real duplicates found | Deslop | jscpd |
|---|---|---|
| All (789 pairs) | 787 (99.7%) | 408 (51.7%) |
| Exact copies (106 pairs) | 106 | 85 |
| Renamed copies (251 pairs) | 251 | 84 |
Read these numbers with their limits:
- The judged pairs came from Deslop. The registers were built by judging candidates Deslop reported, so they favour what Deslop finds.
- jscpd reports pairs Deslop does not. Of jscpd's 8,666 pairs, 3,507 have no matching Deslop finding. Nobody has judged them, so they count neither as Deslop misses nor as jscpd false positives.
- Precision is not compared. The 11 repositories hold only 8 judged non-duplicates; neither tool reported more than one of them.
- jscpd is much faster. It scanned all 11 repositories in 1.0 s with a 194 MiB memory peak; Deslop took 194.6 s with a 1,845 MiB peak.
- The Deslop binary was a local build of 14 November 2026 whose commit was not recorded.
The full report and the script that produced it are in the repository. A fair precision comparison needs a judging pass over a sample of jscpd's own pairs.
How the duplication percentage is calculated
The duplication percentage measures how much code the reported duplicates cover. It says nothing about whether those duplicates are correct.
duplication_percent = clamp(100 × duplicated_loc / analysed_loc, 0, 100)analysed_loccounts every physical line in analysed source files, including blank and comment lines.duplicated_loccounts the lines covered by reported copies in each file. Overlapping ranges count once.- Same shape, different content findings are informational and add nothing to duplicated lines, files, mass or the CI gate.
- Copies hidden by
report_hideor a generated-file banner add nothing to duplicated lines, but their files stay inanalysed_loc. Useexcludeto remove a file entirely. - Folder percentages divide summed duplicated lines by summed analysed lines; they are not averages of file percentages.
Rust computes every percentage, in report_metrics.rs; editors only display it. A false positive inflates the percentage and a missed copy lowers it.
How the CI gate works
Set --fail-over <percent> or [threshold] max_duplication_percent (the flag wins). The run fails only when the measured percentage is greater than the ceiling: it writes the reports, then exits 3. --no-fail-over disables the gate for one run. With --diff and --only-changed, the gate measures only the lines the diff added, while still matching them against the whole tree. See Configuration.